
AI Servers & GPU
accelerated compute for training and inference
Multi-GPU platforms engineered for the thermal, power, and interconnect demands of modern AI — from single-node inference to rack-scale training clusters.
The AI server & GPU brands we source
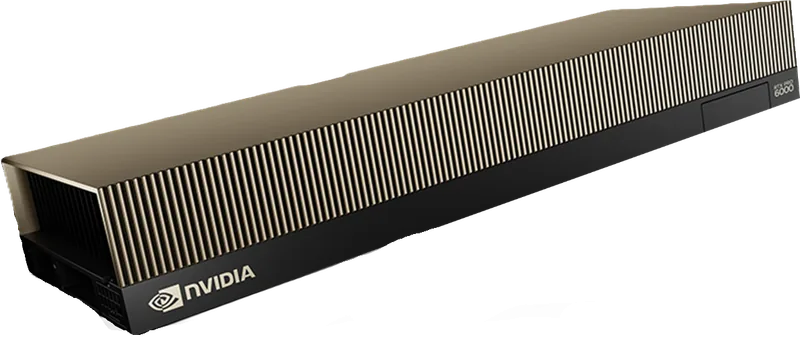

NVIDIA data-center GPUs and HGX baseboards — the accelerators inside every AI platform.
- Up to 141GB of GPU memory per card
- H200 NVL, H100 NVL, RTX PRO 6000 Server Edition and L40S sourced by part number
- Verified for slot fit and power envelope
- Up to 3 years of warranty coverage
- New-sealed and certified refurbished options
- Delivery to 14+ countries
- Quotes returned in 17 minutes on average
From single-node inference to rack-scale training
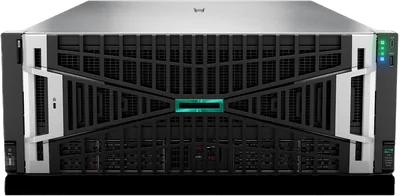
Inference Nodes
HPE ProLiant DL380a
Right-sized 2–4 GPU servers for real-time model serving at the edge or core.
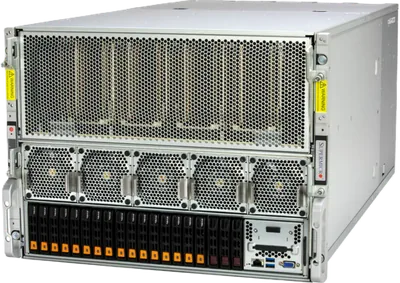
Training Servers
Supermicro 8-GPU SuperServer · Dell PowerEdge XE9680
Dense 8-GPU platforms with NVLink/NVSwitch for large-model training.
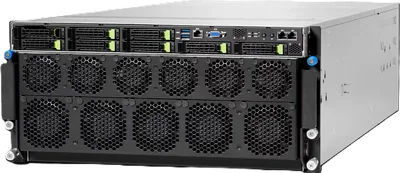
HPC & Simulation
HPE Cray XD · Dell PowerEdge XE8640
Balanced CPU-GPU nodes for scientific computing and rendering.
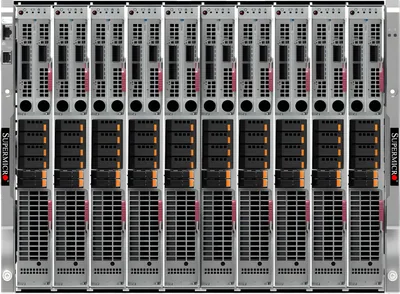
Cluster Building Blocks
Supermicro SuperBlade
Rack-scale reference architectures with high-speed east-west fabric.
Built for the whole AI pipeline
Data
High-throughput storage and networking to keep GPUs fed.
Train
Multi-GPU nodes with NVLink for large-scale model training.
Infer
Latency-optimized serving nodes close to where data is created.
Scale
Reference-architecture clusters that grow predictably.
Architecture at a glance
- Accelerators
- NVIDIA H100 / L40S / A-series & equivalents
- Interconnect
- NVLink / NVSwitch, PCIe Gen5, 400G fabric
- Cooling
- High-static-pressure air & direct liquid cooling
- Power
- High-wattage redundant PSUs, rack PDdU planning